Opinion
Opinion posts from the AIHubMix team.
What GPT-6.1 Sol Really Costs: Beyond the $2 / $10 Price Tag
GPT-6.1 Sol has the same list price as GPT-6 Sol: $2 per million input tokens and $10 per million output tokens. Your actual bill depends on four other things: how often you hit the cache, whether you cross 272K input tokens, which service tier you use, and how many reasoning tokens the model burns. This post goes through each one. The full price list Standard rates (per 1M tokens) GPT-6.1 SolGPT-6 SolGPT-6 AstraGPT-6 LunaInput$2.00$2.00$10.00$0.10Cached input$0.10$0.20$1.00—Cache writes$
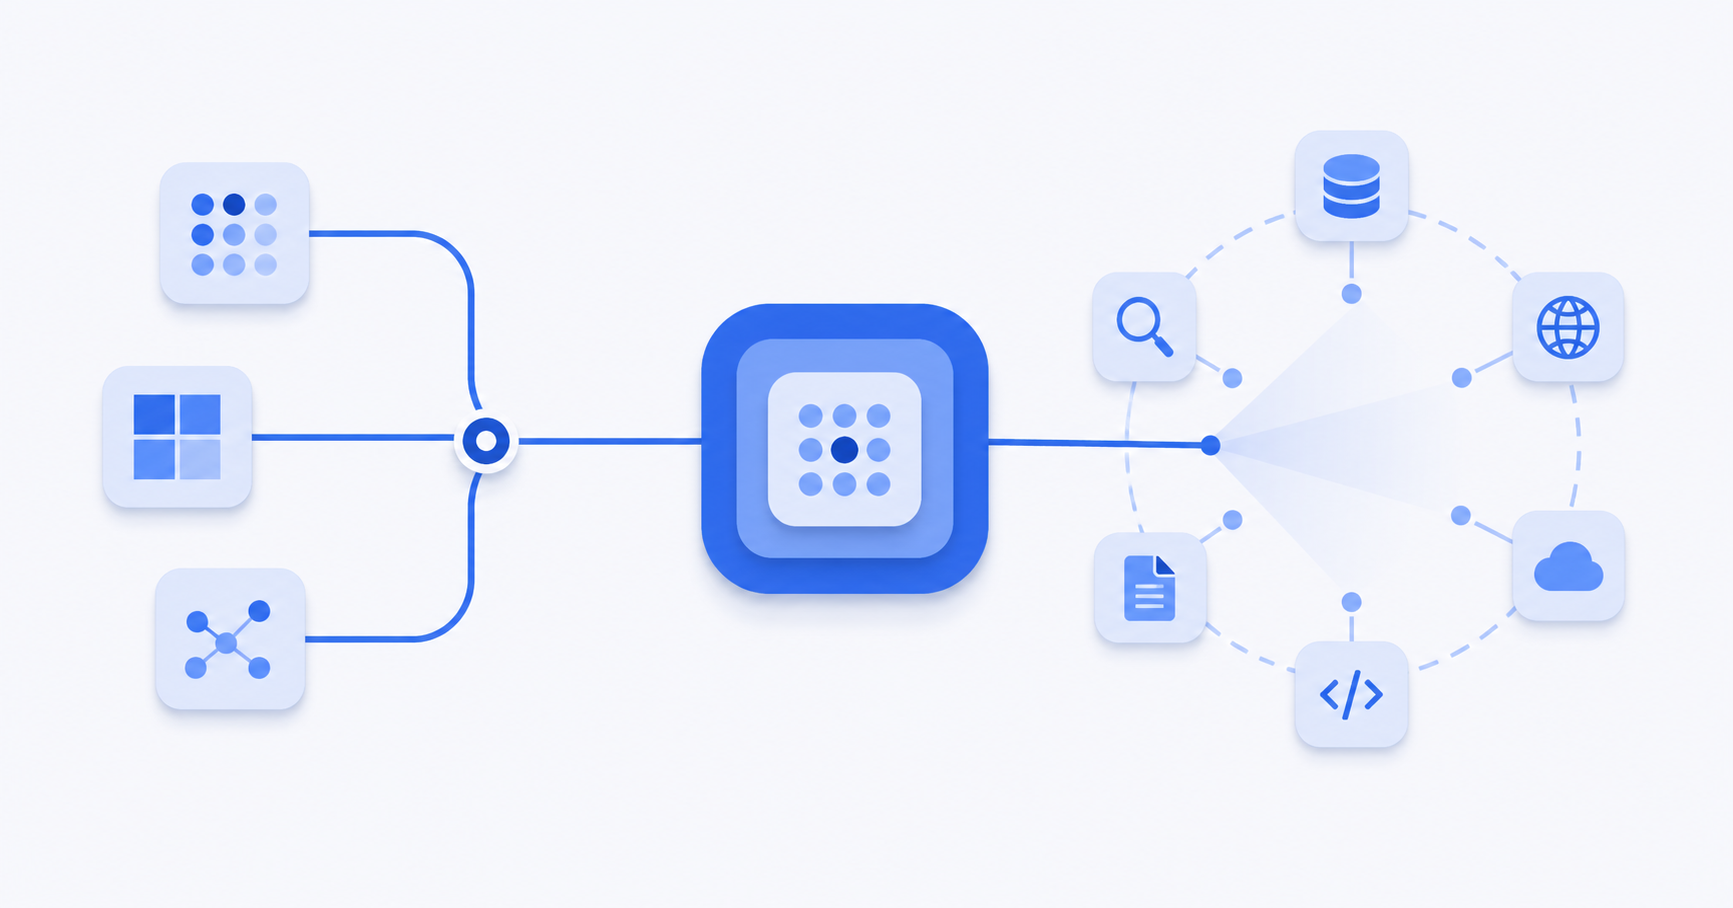
AI Agent Architecture: Model Routing and Tool Discovery
Learn why production AI agents need two integrations: AIHubMix for real-time model routing and Monid for runtime tool discovery and API access.
DeepSeek V4 Flash Was Degraded Today. Here’s Why Multi-Provider Failover Matters
On August 4, 2026, DeepSeek’s official status page recorded two API degraded-performance incidents. The first incident lasted 1 hour and 18 minutes, from 02:02 to 03:20 UTC, and affected DeepSeek V4 Flash, V4 Pro, and Expert Mode. The second incident lasted 36 minutes, from 03:43 to 04:20 UTC, and affected the DeepSeek V4 Flash API. Both incidents have since been resolved. OpenCode also reported that DeepSeek Flash was experiencing capacity issues due to unprecedented demand. However, DeepSeek
GPT-5.6 Is Live: Prompt Caching Billing Changes Explained
July 2026: GPT-5.6 gpt-5.6-sol / terra / luna on AIHubMix: 1.05M context, 1.25x cache writes, prompt_cache_key, explicit breakpoints, vs Claude caching.
